
messy code smells from claude code
imo we're just building a graveyard of bad commits. 89% of those issues were just code smells and nearly 23% stay in the repo long after the merge.>AI-authored commits can remove existing smells, showing that generated code can both create and repay debt.
it's fine until the technical debt becomes too heavy to crawl.
article: https://dzone.com/articles/ai-generated-pull-request-debt
scans aren't runtime tests
People keep treating green status lights as gospel when they're basically just checking if the routes exist in the AST.>A route that was detected and emitted is a route the code mounts, not a behavior that was verified.
It's like looking at a perfectly kerned header and assuming the whole page's hierarchy is correct without actually reading the content. We need to stop
found this here: https://dev.to/jeff_pdc/what-a-successful-code-scan-does-not-prove-18dn
organizing breadcrumblist schema by importance
been seeing way too much junk in the breadcrumb trail lately. some devs are just dumping every single category level into the markup even when it makes no sense for the user. im thinking of trying something different this week and stripping out the non-essential parent nodes from the json-ld entirely. if its not part of the actual click path on the page"@type": "ListItem","position": 1,"name": "Products"
mostly just trying to reduce the bloat in the crawler's render budget. might be a stretch but worth a shot on one of my smaller sites.
fixing json parser errors with cdm
finally moving away from those shitty prompt hacks for json outputs. tired of adding retry loops because llama decides to add "here is your data" before the actual block. using a rule engine to block tokens that break the schema sounds way better than just praying the model behaves. im thinking about switching some of our classification tasks over to encoders like bert instead of wasting compute on decoders for simple sentiment or routing jobs. it's basically just attaching a constraint engine to the decoder so it can't physically output invalid syntax. might save us some headache with those broken pipelines. anyway, seeing if this actually scales without killing latency.more here: https://dzone.com/articles/constrained-decoding-models-explained
googlebot rendering delays on heavy css files
been seeing some weirdness with how googlebot handles massive stylesheets lately. its like it just ignores half the rules if the file is too big so the rendered html looks totally broken compared to what i see in chrome.>the page looks fine in my browser
im looking at the same thing but clearly isnt getting the full picture. must be a timeout or something during the rendering phase.
schema markup issues with sameas urls
stumbled onto another client using absolute paths for their social links in the sameas array instead of just clean urls. it's"@type": "Person","sameAs": ["https://twitter.com/user/", "https://facebook.com/user"]
the inconsistency is driving me mad.

subpage urls not showing in search console
been staring at gsc for three hours and its just flatlining for these deep subpages. tried adding sitemap links manually but nothing is changing.>not appearing in index
tried setting the canonicals to point directly to the parent but it didnt help either. maybe some weird crawl budget issue with the way the directory structure is nested?

aggregateasurclink property issues
been digging through some search console data for a client and noticed those aggregateasurclink markup errors are popping up everywhere lately. it's not even an error in the validator but google is just ignoring the link entirely. tried adjusting the nesting structure to see if it helps but nothing's changed. seems like they're being way more picky about how the related links connect to the main entity. it makes the whole review snippet section look broken when it doesn't render right. has anyone managed to get these actually recognized lately?
fragmented robots. txt via subdirectories
Trying to manage separate robots.txt files for different subdomains but Googlebot keeps hitting 404s on the root one. I tried adding a single x-robots-tag to the headers, but it's not picking up the disallow rules for the /archive/ path.
lcp issues with priority hints on hero images
trying to fix lcp on this client site but adding fetchpriority="high" to the main banner is actually making my cls worse. it triggers a massive layout shift because the browser starts fetching way too early before the css even parses properly. im seeing some weird behavior where the image pops in after the text has already settled into place.>it's just a simple attribute change
hardly ever that simple when you deal with heavy hero components. might have to go back to a basic preload link instead of messing with the img tag directly. rip my afternoon
latency budget for retrieval pipelines
stop trying to find the perfect search result if it takes forever lol. just use 150ms for lexical/metadata then move to semantic reranking before you hit that one-second wall clock deadline.>return the best cited matches you have rather than blocking intake on a second attempt
it's basically hard deadlines or nothing, otherwise your p99 is going to be a disaster. wonder how much this actually helps with tail latency in production though.
found this here: https://dev.to/frozensigh2853916/how-to-design-retrieval-architecture-for-insurance-intake-under-time-limits-4mc1
font-display swap causing unexpected layout shifts
been looking at some recent lcp reports and noticed font-display: swap is absolutely killing my cls scores on mobile. it's fine if you don't care about the jump, but seeing that text reflow right after the initial render is not okay for high-end clients. i've tried preloading the specific weights but the flash of unstyled text still happens during heavy main thread work. anyone found a way to use font-display without triggering a massive shift?
technical seo is such a headache
it's annoying how easy it is to accidentally leave a noindex in your robots meta tag or mess up canonicals without even realizing it. i was looking at some stuff about checking soft 404s and redirect chains with curl, but honestly, who has time to manually audit every single header when you've got actual work to do?link: https://www.freecodecamp.org/news/fix-common-technical-seo-issues/
css content property and crawler visibility
Been seeing some weirdness with how certain headless browsers interpret text inside pseudo-elements lately. If you're using it for decorative icons or breadcrumb separators, try checking if the content actually shows up in your raw fetch logs.
ai churn is getting out of hand
code churn is basically projected to double this year because everyone's just copy-pasting whatever the model spits out. half of those chatgpt answers for stack overflow are straight up wrong but people still fall for them because they sound confident. honestly feels like we're just building a mountain of technical debt that no one will know how to fix when it finally breaks.found this here: https://dzone.com/articles/ai-code-deterministic-validation
claude code running as an mcp server
it's pretty weird that you can just flip the whole thing around with claude mcp serve. instead of it just grabbing external tools, now some other app can call into claude to use its own tool definitions and schemas. i'm not sure how much overhead this adds when running as a local subprocess via stdio, but the idea of reusing the same logic for both client and server roles is clever. anyone tried hooking an actual custom client up to this yet?more here: https://dev.to/_94be737e156beb4d74df2/claude-code-mcp-deep-dive-8-from-mcp-client-to-mcp-server-26n
mongoDB query performance
Found some decent info on catching COLLSCAN stages before they tank production. Checking executionStats with. explain("executionStats") makes it pretty obvious when you're scanning a million docs just to find one email.>totalDocsExamined: 1000000
Still not sure how much overhead we'd deal with if we started adding more compound indexes to the orders collection though.
article: https://dev.to/moshfiqurrahman/mongodb-indexing-explained-make-your-queries-100x-faster-3cm1

fargate making pods their own node unit
aws is basically stripping away everything we know about worker nodes with this fargate setup. it's all handled via an admission webhook that just reroutes things if they match a profile.>the pod is the unit of infrastructure
don't see how anyone handles complex networking or sidecars when each pod gets its own dedicated environment and eni. it sounds like a nightmare for debugging anyone actually running production with this yet?
https://thenewstack.io/serverless-kubernetes-aws-fargate/

gateway logic for rag setups
finally saw someone admit that calling openai directly is just burning money. they're using a fastapi proxy to handle semantic caching and grounding checks so users don't get hallucinated hr policies.>It doesn't say "I don't know"; it just generates something plausible.
imo skipping langchain for native mongodb vector search is the only way to actually debug this stuff when it breaks. im skeptical about how much latency that extra hop adds though.
found this here: https://dzone.com/articles/rag-architecture-patterns-proxy-caching-routing

ai finding php2shell bugs is wild
wiz used 'gemini 4 argon' and 'gpt-5.6 sol' to basically gut php's memory safety. apparently it's a use-after-free mess that hits everything from wordpress to drupal since the engine is still stuck in c. seeing ai uncover flaws that sat there for like a decade makes me wonder if our entire tech stack is just one prompt away from a total wipeout lol.article: https://thenewstack.io/ai-php2shell-disclosure-framework/
kotlin migration debt is real
im staring at hundreds of thousands of lines of java and thinking about that converter tool. totally wish i'd moved to data classes earlier so we could scrap all this boilerplate. if you dont do it when the codebase is small its basically impossible once the monolith takes over.article: https://dzone.com/articles/switching-to-kotlin
client dashboards vs monthly reports
jetoctopus is trying to sell this idea that you can just link gsc, ga4, and logs all on one view so clients don't get lost in status codes. it's basically saying stop sending them deep crawl depth charts and instead give them a dashboard they can poke at whenever.>Every report type below already exists inside JetOctopus
it sounds nice but i've seen these "on demand" dashboards turn into another ticket for the dev team when something breaks. plus, if you don't include that one-line takeaway like it says, you're just sending them a bunch of meaningless charts again. building this once is fine, but managing the commentary every month sounds like
found this here: https://jetoctopus.com/how-to-build-a-technical-seo/
Screaming Frog vs. Xenu for detecting 404s in large crawls
Been moving most of my heavy site audits over to Screaming Frog lately because Xenu just chokes on anything over a few thousand URLs. It's much better at handling the modern JS-heavy stuff without me having to manually configure every single crawler setting. If you're dealing with massive subdirectories, stick to the paid version so you don't hit that memory ceiling.spoaderXenu is basically a relic at this point/spoiler
schema drift controls for chatbot APIs
The idea of using a contract pipeline to handle JSON validation at the boundary sounds fine on paper, but I'm not convinced it solves the actual messiness. Seeing that they track an explicit state like 'observed' or 'unknown' instead of just forcing a value is interesting, but how do you prevent the schema from becoming a nightmare to maintain? It's easy to talk about preventing silent search defects with field-level rejection rates, but I wonder about the latency hit on long context windows. If you're running this for something like 'catalog. v3', I'd need to see how much the repair step actually drags down the throughput. Also, how long did they run this test for? It's hard to tell if these low first-pass output rates are a temporary fluke or just the cost of doing business with inconsistent prose. Hard to know if this scales without seeing some actual error distribution data over a larger sample.article: https://dev.to/daltonreed1289/nodejs-chatbot-api-compare-long-context-good-quality-via-schema-drift-controls-2ed6

java schema sync without migration scripts
Managing those huge folders of V142. sql files is such a nightmare during merges. It's always some mess of conflicting scripts when two people branch off main at the same time. I saw this library SchemaSynchronizer that tries to do it declaratively like Terraform does for infra. You just keep a single schema-definition.json file and let it figure out the diff.{ "tables": { "work_items": { "columns": [ {"name": "id", "definition": "UUID PRIMARY KEY"} ] } }}It looks clean on paper, but I'm worried about what happens during a complex refactor. If it just reconciles the state, it might try to drop and recreate things by mistake. Never trust an automated tool to handle heavy data migrations without checking the plan first.
more here: https://dzone.com/articles/declarative-database-schema-management

fx integration for T3 Code
another thing to manage in my dev workflow. finally got fx inside the T3 desktop and web clients with that auto mode enabled.>The built-in fx provider supports Supervised and Auto modes
it's probably going to be a nightmare once it starts hallucinating changes in my control plane settings. anyone actually using the mobile version for this?
found this here: https://vercel.com/changelog/fx-is-now-available-in-t3-code
gemini 4 argon fixing google's adk codebase overnight
it's wild that argon managed to drop package import time by 21% just by running for eleven hours without any supervision. i'm skeptical it could actually trace all those cross-module references without getting lost in the noise of a real production repo.more here: https://www.infoq.com/news/2026/10/google-argon-optimizes-adk/?utm_campaign=infoq_content&utm_source=infoq&utm_medium=feed&utm_term=global
unnecessary nesting in breadcrumblist schema
found another client site where they're wrapping every single breadcrumbitem inside its own nested list instead of just using one flat array. it's a total mess for the crawler and makes the lcp look spoilergarbage/spover.
timezone testing is such a headache
jetlag looks pretty decent for catching those stupid toISOString() bugs where everything breaks at 9pm in la. it basically wraps your test command so you don't have to manually mess with locales or offsets. caught some nasty stuff like:> Code that assumes offsets are whole hours, or rounds getTimezoneOffset() / 60, is 15 to 45 minutes off.
it even checks for weird stuff like leap years and daylight savings shifts in places like kathmandu. tbh i'm skeptical about how much it'll slow down my CI pipeline if i run ten different destinations every time. still better than finding out a billing module is broken because of a 45 minute offset during a production deployment. wonder if it handles decimal separators for different locales properly though.
https://hackernoon.com/how-to-test-your-code-across-time-zones-and-dates-with-jetlag?source=rss

querying vcf files with http byte range requests
Using byte range requests to pull parts of compressed VCF files directly from S3 sounds pretty efficient for avoiding massive transfers. I wonder if bcftools can handle the overhead once you scale up the number of concurrent Lambda functions hitting the same objects.article: https://www.infoq.com/news/2026/10/csiro-serverless-genomic-variant/?utm_campaign=infoq_content&utm_source=infoq&utm_medium=feed&utm_term=global
lru cache bloat in json-ld injection
tried stripping out all the non-essential properties from the product schema but the script's still bloating the initial payload by about 40kb. it's making the lcp jump because the parser is choking on the massive string of nested object data.{"@context": "https://schema.org","@type": "Product","additionalProperty": [ ... ]}anyone found a way to prune these dynamically without breaking the rich result validation?

service worker registration bloat on heavy single page apps
I've been looking at our latest build and the service worker is grabbing way too much during the initial install. It's trying to cache every single chunk from the build manifest instead of just the critical path assets.>It's fine as long as the user has a fast connection.
self.addEventListener('install', (event) => {event.waitUntil(caches.open('v1').then((cache) => {return cache.addAll(['/', '/main.js', '/styles.css']);}));}); 
aggregateornotproperty bloat in product schema
people keep adding every single possible property to their product markup thinking it's some kind of magic boost. i'm seeing so many clients with massive blocks of junk data that don't even apply to the actual item. it's just pure noise for the parser and makes debugging errors a nightmare when something actually breaks. if you aren't using the specific value, don't include the key at all. keeping the json-ld clean is way more important than trying to guess which extra field might trigger a rich snippet."additionalProperty": [{"name": "color", "value": "blue"},{"name": "size", "value": "large"}]it's better to stick to the basics and let the search engine do its job without the clutter. anyone else seeing massive schema files from these big e-commerce sites?
image attribute alt text and lcp bloat
I was looking at some old e-commerce builds yesterday and noticed how much we overlook the impact of massive alt text strings on the critical path. Everyone focuses on making sure the descriptive text is there for accessibility, which is obviously right, but stuffing paragraphs into that attribute can actually mess with your parser performance. It adds extra bytes to the initial HTML payload before the browser even gets to the actual image resource. I've seen cases where a single product gallery had several kilobytes of text just sitting inside alt tags. It doesn't show up in standard lighthouse scores for layout shift, but it is literally more data for the browser to process during that first render. We should try an experiment this week on any site with heavy media. Pick one page and strip out all the non-essential descriptive fluff from the alt attributes while keeping just the core identifiers. Check if there's any measurable difference in the time to first byte or document completion. It is a small tweak, but it helps keep the DOM light.
decomposing decisions instead of functionality
Thinking about moving from microservices to agents feels like another massive headache for observability. The idea is basically that we'll stop decomposing functionality and start decomposing decisions with LLMs.>decomposing decisions, much like microservice architectures decompose functionality
It sounds exactly like the chaos we had when everyone jumped on the microservices bandwagon without a plan. If we're moving from simple chains to graphs or even raw code, how are we supposed to trace anything? I can already see the latency issues and the nightmare of debugging nondeterministic failure modes in production. It's probably going to be just another layer of complexity to manage.
https://www.infoq.com/articles/agentic-ai-architecture-article-series/?utm_campaign=infoq_content&utm_source=infoq&utm_medium=feed&utm_term=global
security gateway for genai seems like another layer of latency
another day, another way to slow down everything with extra checks. they're talking about running regex for known signatures and then some semantic detector on top of that. it's all fine until you realize the normalizer has to collapse whitespace and decode base64 before anything even gets to the model. adding a risk score between 0.0 and 1.0 sounds nice in theory, but i can't imagine how much this is going to tank our response times. if we're doing pii scanning and sanitizing everything at the boundary, we might as well justmore here: https://dzone.com/articles/genai-security-gateway

systeme. io to pipedrive webhook mess
The lack of a schema for 'Systeme.io' payloads is such a pain. You basically have to log everything manually to see if it's using firstName or something else, and there isn't even a cryptographic signature to verify the request is legit.const app = express();app.use(express.json());
Implementing some middleware with Node.js seems like the only way to avoid
link: https://dev.to/holly_ai/integrating-systemeio-and-pipedrive-apis-a-developers-guide-to-webhook-handling-and-data-sync-3h69
agent transitions are where the actual work happens
The hype around agents ignores how much is still just standard engineering. Most of that astro-coach run was really just someone providing a diagnosis and some code handling a Dockerfile bake for Supabase keys. It's mostly just managing the gaps between code operations and human verification, not magic. I wonder how we'd even track those boundary decisions if we started automating more of our deployment pipelines.found this here: https://hackernoon.com/your-agent-workflow-is-mostly-code-and-people?source=rss
missing aggregateRating property in local business schema
been cleaning up a mess for a local cafe all morning. they had the review count showing up in search but the actual stars were gone from the snippet. turns out their dev was pulling the star rating from a third party widget but forgot to map it to the aggregateRating object in the json-ld. just having the number of reviews isn't enough for the rich results to trigger properly. you need both the reviewCount and the explicit ratingValue.>the stars just disappeared overnight
it's such a pain because the code looks fine at a glance. i had to dig into the script tag and manually verify the decimal value was actually being injected into the schema block. if the widget fails to load or returns a null, the whole property breaks. fixed it by adding a fallback value so it doesn't

sitefetch delays on large product catalogs
been looking at some crawl logs from a massive ecom client lately. everything looks fine until you hit the deep paginated stuff. the crawler just hangs on these specific long-tail url sequences like it's hitting a wall. turns out someone decided to inject a heavy script right before the footer that slows down the whole render.>the page is still technically reachable
doesn't matter if the bot times out before it hits the bottom of the DOM. we're seeing massive latency spikes on these deep links. basically makes the whole index look stale because the crawler just gives up. it's always a third party tracking script
cleaning up 28k lines with knip
saw someone talking about stripping out 28k lines of code using knip. sounds great in a vacuum but i'mfull read: https://tkdodo.eu/blog/dead-code-shouldnt-exist

ai fitness functions sound like overkill
using ai for semantic drift check feels superhttps://www.infoq.com/minibooks/evolutionary-architecture/?utm_campaign=infoq_content&utm_source=infoq&utm_medium=feed&utm_term=global
automated pr reviews are killing the point of reviewing code
saw that faros ai report saying merged prs without review jumped over 76%. it's getting ridiculous how much of the work is just being rubber-stamped by bots now.>AI review took over bug-finding.
the tool can check if the syntax is right but it doesn't know if we should be using a token bucket or a sliding window for this specific feature. i don't see how having a second agent push back on the first one actually solves the lack of human intent in the diffs. anyone else feeling like they're just auditing logs instead of actual code?
https://thenewstack.io/review-decisions-not-code/
security shouldn't be an afterthought
been thinking about this all morning because i just saw another dev trying to patch cors after the api was already live. it's so exhausting watching teams treat security like a layer you just slap on top of existing code once something breaks. you can't just add it later without breaking everything.>Security isn't something you add to software. It's something you build into it from the beginning.
it's much easier to handle things like encryption standards or field-level masking at the domain layer before the first pull request even exists. if you aren't doing threat modeling during architecture, you're basically just waiting for an incident report to hit your inbox. i don't know how anyone manages to maintain a clean pipeline when they're constantly chasing vulnerabilities in production. it feels like people think 'secure by design' is some magic trick instead of just basic engineering discipline. it's actually just common sense but nobody wants to do the extra work upfront. does anyone here actually get time for a proper threat model before shipping, or are we all just winging it?
found this here: https://www.freecodecamp.org/news/secure-by-design-engineer-security-into-architecture-before-writing-code/
fragmented canonicals on paginated category pages
Spent all morning digging through GSC for this client. They have these huge e-commerce categories where every single page has its own canonical pointing to itself instead of the main hub. It's making the crawl budget look like a disaster because Google is just wandering through endless filter combinations.>Everything should point back to the root category
That's what the dev team keeps saying, but they don't realize how much junk we're feeding the index. If we don't clean up these self-referencing tags on page 2 and beyond, we're just wasting resources. I've seen it happen where a single deep filter creates a thousand new URLs that shouldn't even exist. It's not even about the weight of the pages, just the sheer volume of redundant paths.
storing context for architectural choices
spent too much time digging through slack threads trying to figure out if we used REST or gRPC for that one service. it's annoying how easy it is to lose the 'why' behind a choice when people leave, but keeping ADRs in the repo might be too much overhead for small changes.https://hackernoon.com/architecture-decision-records-adrs-a-beginners-guide?source=rss

openai codex cli for terminal
finally getting something that doesnt force me to leave my shell. looks like it runs locally but you still gotta hook up an api key or your chatgpt plus account. might try the npm install later but im skeptical about how much latency it adds when running heavy scripts. its basically just another way to use codex inside vs code or cursor too.article: https://dev.to/victor_hugo_a07c85ac09eea/conheca-o-codex-cli-agente-de-codigo-da-openai-no-terminal-284k

imageof property type mismatch on product schema
I'm seeing some weirdness with how Google Search Console handles nested objects when I try to use an array for the same property. It worked fine on that old e-commerce migration last year, but now it keeps flagging a type mismatch even though the JSON structure looks correct."offers": {"@type": "Offer","price": "29.99"} 
copilot custom instructions are getting weird
another day of microsoft trying to make their ai act like a senior dev. now you can apparently feed it custom instructions and skills for your repo so it actually knows what it is looking at. they are pushing this mcp server thing too, using playwright to let the agent crawl stuff or whatever. sounds great until you realize how much garbage context you end up bloating the prompt with. i tried adding some basic repo rules last week and it just hallucinated more than usual. if we start connecting every tool via mcp it is just going to be a nightmare for latency and debugging. plus the security implications of letting an agent run playwright on your codebase are not even funny. probably just another way to make developers lazier while paying a monthly subscription. i doubt this actually helps with complex logic without breaking something else in the process.more here: https://github.blog/ai-and-ml/github-copilot/github-copilot-app-for-beginners-how-to-teach-copilot-about-your-codebase/
nigerian postcode hallucination problem
llms are still spitting out 6-digit codes when nigeria moved to that 11-character format like EK-01-A03-FK-01. ime it's a mess for anyone running checkout flows or validation scripts. using an mcp server to force deterministic checks is the only way to stop these agents from just making stuff up.>The model proposes a postcode, and deterministic code decides whether it's well formed
full read: https://www.freecodecamp.org/news/how-to-stop-an-ai-agent-from-inventing-nigerian-postcodes/

aes-gcm is finally killing cbc
still seeing too many devs using cbc for session tokens and it's asking for a padding oracle attack. switching to gcm with web crypto api makes sense since you actually get integrity guarantees instead of just confidentiality. ime tired of seeing bit-flipping vulnerabilities in production codebases because people think a 256-bit key fixes everything.more here: https://dev.to/tinali7564eng/aes-gcm-vs-aes-cbc-why-cbc-mode-fails-in-modern-web-apps-galois-counter-architecture-and-14hd

erroneous itemlistelement ordering in collection schema
been looking at some of our bigger e-commerce clients lately and notice it's a mess. people keep dumping products into an itemListElement array without even checking the order matches the actual page render. it's such a lazy mistake to just loop through a json object and hope for the best. if the schema says product A is first but the crawler sees product B, you're asking for trouble with rich snippets. i tried testing a fix where we explicitly sort the array based on the visible id before generating the script tag.const sortedItems = items.sort((a, b) => a.position - b.position);renderSchema(sortedItems);
it's not rocket science but it definitely helps keep the data clean. i saw one dev claim
>the crawler is smart enough to figure out the order
which is totally
schema is more than just templates
most plugins just dump random markup on pages without actually linking anything together. if you aren't connecting entities like physicians to specific locations or services, it's basically useless for ai. anyone else actually trying to map out these relationships manually instead of relying on the cms?more here: https://www.schemaapp.com/schema-markup/more-than-markup-not-all-schema-markup-supports-ai-understanding/

next. js app router schema validation
Been thinking about how much more work we're going to have to do with JSON-LD once AI scrapers start relying on it even harder. Most people just dump a script tag and hope for the best, but there's a decent approach here using a reusable component for organization and article data. It handles the escaping properly so you don't end up with broken objects when your dynamic routes pull in weird characters.>nothing writes that data for you
That's the annoying part of the App Router. You have to manually build these blocks for every single page type. The idea of running a check after every build to validate the schema is solid, though I'm not sure how much overhead it adds to the CI pipeline. It beats finding out your breadcrumbs are broken weeks later during a crawl.
at least it isn't manual testing
link: https://www.freecodecamp.org/news/nextjs-json-ld-structured-data/

disabling jquery mobile via robotstxt for non-essential assets
been seeing way too much crawl budget waste on legacy sites lately. some old enterprise client still has jquery mobile scripts loading deep in their subfolders and it'sUser-agent: *Disallow: /assets/js/jquery-mobile/
it helps keep the focus on the actual content instead of parsing useless library code. does anyone else still deal with these old mobile scripts hanging around?

log files are useless if you can't actually query them
the sheer scale of their logs makes it impossible to do any real analysis without something like JetOctopus. they were only keeping data for 7 to 14 days, which is a joke when you're trying to figure out if a template change from months ago messed up your rankings.>two weeks of history is enough to notice that something broke on Tuesday. it is not enough to prove that a template change shipped in march is what moved googlebot in may
it's fine for small sites, but i don't see how anyone manages crawl budget waste on a massive marketplace without seeing those long-term patterns. does anyone here actually rely on raw logs for anything besides checking 404 spikes?
more here: https://jetoctopus.com/case-study-large-marketplace/

hidden machine dependencies are everywhere
>the developer workstation becomes an undocumented dependencyit's pretty annoying how much people ignore things like host time zones or locale settings until something breaks in production. i've seen too many devs rely on the default jvm behavior instead of just being explicit with ZoneOffset. UTC and stuff like that. does anyone actually bother with reproducible-builds for every single microservice or is it just a pipe dream?
full read: https://dzone.com/articles/works-on-my-machine-architecture
nginx rewrite loop on sitemap urls
stuck in this nightmare with an nginx config change for a client. everything looks fine in the browser but logs show a redirect loop specifically for the xml files. tried stripping the trailing slash rule but it didn't fix anything.location ~* \.xml$ {rewrite ^(.*)/$ $1 permanent;}it's acting like the sitemap is hitting a different block entirely.
>the crawler just sees a 301 loop and gives up. checked the upstream headers and they look clean, so i'm losing my mind. tried testing with curl but even that returns the same mess. turns out the legacy regex in the main server block is catching them too.

aws eventbridge central bus mess
finally looks like we can stop chaining cross-account rules like some kind of spaghetti nightmare. i'm interested in that synchronous lambda invocation though because it might actually let me scrap the sqs buffer i've been using for everything. anyone tried testing the new deduplication yet?full read: https://www.infoq.com/news/2026/10/aws-eventbridge-scaling/?utm_campaign=infoq_content&utm_source=infoq&utm_medium=feed&utm_term=global

schema gaps aren't always broken code
It is annoying how much time we spend checking for green ticks in the rich results test while ignoring actual eligibility. We can have perfect JSON-LD on a product page but still lose the price and star rating if the data isn't complete enough for Google. I noticed it also mentioned that FAQ snippets are basically dead now so there is no point in debugging those. The real issue is probably our out of stock items or deep filtered pages where the markup exists but doesn't meet the quality guidelines. We should probably run a wider audit on the catalog instead of just testing single URLs manually. I wonder if we can automate a check for missing required properties across all variants.more here: https://jetoctopus.com/how-to-find-and-fix-your-rich-snippet-gaps/
itemscape property mismatch in schema markup
im looking at this client site where they got all their product schemas for different regions but they forgot to sync the itemscape property across the subfolders. it looks fine in the rich results test but google is just ignoring the price data because of the mismatch. if u dont match the exact same value in every single schema block on the site, its basically useless. check your url strings very carefully before deploying. had to rewrite a massive loop for them because they were pulling dynamic values that changed slightly per locale. it took me three hours to find one extra space
css content property for hidden decorative elements
was messing with a client's lcp scores today because their devs love adding unnecessary div wrappers for simple icons. it's driving me crazy. if you can move that decoration into the css, do it. i've been using the content property on pseudo-elements to keep the DOM clean and avoid extra nodes that bloat the render tree. it's a small win but helps when you're fighting for every millisecond of main thread time..icon-marker::before {content: "";display: inline-block;width: 12px;height: 12px;background-color: #ff0000;}don't just keep nesting empty spans for the sake of it. keep the markup lean. i saw a site yesterday with three levels of nested divs just to show a single bullet point. it's honestly painful to look at. does anyone else actually bother auditing the DOM depth for lcp or do you just ignore it and hope for the best?

google's grouping their youtube tutorials
google is finally trying to organize all that search central chaos into actual playlists instead of just dumping videos in a pile. they're even promising deep dives on crawl budget optimization and rendering stuff, but it'll probably just be the same old advice we've seen for years.>managing crawl budget, rendering considerations, and large-scale debugging
it's basically just a repackaged version of what's already in the docs.
article: https://developers.google.com/search/blog/2026/10/seo-learning-paths

debugging debt from ai coding agents
im seeing this all over. engineers are spending nearly 17 hours a week just fixing bugs because nobody actually understands what the ai wrote.>35% of generated code reaches production before the team has fully understood it
it's basically a disaster waiting to happen once you hit complex systems and start dealing with hallucinations in root-cause analysis. im pretty sure we're just building technical debt mountains now.
link: https://www.infoq.com/news/2026/10/survey-complex-codebases-agents/?utm_campaign=infoq_content&utm_source=infoq&utm_medium=feed&utm_term=global
agent memory isn't just about storage
it's annoying how most people treat mcp like it's some magic memory layer when it's really just an interface. you can't just swap mem0 for graphiti and expect things to work because the integration boundary changes everything. i'm still not sure if separating retain, recall, and reflect is actuallyfound this here: https://hackernoon.com/agent-memory-is-an-architecture-decision-from-mcp-servers-to-stateful-agents?source=rss
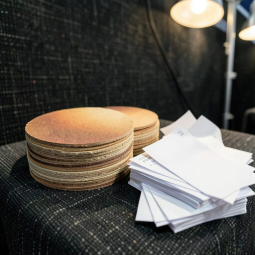
screaming frog at brightonseo again
the screaming frog crew is setting up shop at booth 18 for the october brightonseo event. they're doing that beer mat coloring thing again to win a one year spider license. honestly sounds like a lot of work just to get some software. it's fine if you want to talk about feature requests or the new log file analyser updates but i'm not sure about the greenseo stuff on wednesday. reducing environmental impact via seo is such a niche concept that it feels a bit performative. they're also handing out two week trials of the spider and the log file tool if you happen to wander by. i'll probably skip the coloring contest though. just seems like something for people with way too much free time between crawls. anyone actually planning on going down to brighton this time?link: https://www.screamingfrog.co.uk/blog/brightonseo-october-26/
googlebot crawl budget waste on large resource redirects
been digging through some server logs today and it's a total disaster. we've got thousands of old urls just sitting there redirecting to current paths, which is eating up way too much of the crawl budget for no reason.>redirect chain hell
it's making the actual important pages take forever to get indexed properly.
http 301 /old-category/product-ahttp 301 /new-category/product-a
anyone else seeing a massive spike in crawl errors after cleaning up these legacy redirects?

parsing logs for gptbot is a nightmare
another day of digging through server logs because ga is useless for this stuff. apparently 67% of gptbot hits are just hitting 404s which is such a waste of crawl budget.>most teams have no idea which ai bots visit their site, which pages those bots actually reach or whether the crawler seen in the logs is the real GPTBot or something wearing its user-agent as a mask
im already dealing with enough spoofed traffic without having to cross-reference vendor ip ranges just to see if claude is actually crawling us. jetoctopus claims it handles the filtering but i'd rather not pay for another subscription just to find out our logs are bloated with junk.
more here: https://jetoctopus.com/how-to-track-ai-crawler-activity/
fid is finally dead
google's pulling the plug on fid starting november 1st. they're just leaning into inp for everything now.>stop recording new measurements on november 1st
it's not like we haven't been dealing with inp for a while, but it's weird seeing them officially drop the old metric from speed insights. i'm curious if anyone's actually seeing their real experience score fluctuate because of this.
link: https://vercel.com/changelog/speed-insights-deprecates-first-input-delay-on-november-first

unnecessary lcp element shifts from font-display swap
staring at these reports is killing me. some dev pushed a change to google fonts that's causing massive layout jumps because they forgot to set the proper fallback.
json-ld breadcrumblist id mismatches
been looking at some client logs today and noticed the breadcrumb hierarchy is totally broken in search results. someone went ahead and changed the url structure without updating the @id references in the schema. now it's just pointing to old dead links that don't even exist anymore. it's such a stupid mistake because the markup looks fine at first glance if you aren't checking the actual fragments. i'm seeing this happen way too often with large e-commerce sites moving to new category slugs. don't skip the id validation when you're doing a site migration. anyone else running into broken references after recent cms updates?
sitebulb vs screaming frog for lcp audit
im tired of manually checking every single url for lcp issues. screaming frog is fine if u just want raw data but it basically misses the context of how things actually render. sitebulb is way better for spotting when a huge hero image is causing the delay because its much more visual with the screenshots. i was looking at this one client site where the lcp was tanking and frogs logs didnt show anything weird. then i ran it through sitebulb and saw exactly how the lazy loading was breaking on mobile. turns out the css was just messed up.
patterns in redux and fastapi
saw some stuff about how middleware is basically the same logic everywhere. it's just that one function taking a request and calling next. seen this with 'koa' too where they use it for x-response-time headers. im tired of devs pretending like every framework invented its own unique way to wrap a process when it's just __reused patterns_https://hackernoon.com/middleware-an-architecture-pattern-across-stacks-and-frameworks?source=rss
cra compliance is gonna be a headache for devops
another layer of bureaucracy hitting our pipelines by december 2027. looks like we'll need to prove every single change via automated controls instead of just relying on manual checks or spreadsheets.>The delivery system should prevent them from progressing.
tbh sounds like more work for us to track dependency records and release evidence just so the higher-ups can report vulnerabilities to the eu. it's gonna be a mess trying to move everything from 'ad hoc' to 'enforced' without breaking our current build flow
article: https://thenewstack.io/cra-readiness-starts-codebase/

tokencap's import folding is basically just more magic middleware
another tool to add to the pile. saw this tokencap thing trying to shrink repo snapshots by stripping out all those massive import lists. supposedly it can hit a 58% reduction on raw volume by using some sort of 'import clustering'.> [Folded 18 imports: React, Lucide-React, Lodash]
looks fine for javascript but i'm skeptical about the python stuff. if it messes up any indentation or breaks the whitespace in yaml files then it's useless to me. they claim it uses some 'syntax boundary snapping' so it won't break the tree but regex-based folding always ends up breaking something weird when you have complex decorators or multiline strings. i've seen enough broken builds from "smart" automation to not trust this blindly. probably just another way to save a few bucks on context windows while introducing subtle bugs into the codebase. might be worth a look if it actually handles function signatures right without losing the actual logic.
found this here: https://dev.to/vansharora21/how-tokencap-folds-repetitive-imports-without-breaking-code-syntax-1gpa

vanity metrics for ai dev are trash
just saw a post about some team celebrating 40% more code per sprint because of ai tools. it's always the same story with these dashboards. they were getting all these broken try-catch blocks inline that basically swallowed exceptions and killed their centralized handler. i've seen this exact mess in crawl logs when people just dump junk schema into a template without checking anything. developers are producing more lines but it's mostly justhttps://dzone.com/articles/ai-productivity-code-production-myths
ai code review trials are a mess
another guide on how to run a "proper" ai code review poc without failing immediately. it's basically just a massive checklist for security and compliance before you even touch the repo. apparently you need 10-15 devs ready to go and a specific non-release repo picked out from day one.>The gap is written in one sentence, and each criterion has a way to measure it
sounds like a lot of
link: https://hackernoon.com/how-to-run-an-ai-code-review-poc-a-step-by-step-walkthrough?source=rss
schema. org is basically our only hope for agents
rv guha was talking about this stuff again and it's wild to think we're moving into a fourth major shift after mobile and rss. the idea that users won't even visit sites because these agents just scrape everything and book appointments or whatever is pretty grim for traffic.>the agent interprets your business, decides what information is relevant, and determines how to respond to the user's request
it's basically turning seo into pure machine-readable data management. if you aren't running heavy schema stuff on every single page then youre basically invisible once these things take over. feels like we're just building a giant library for bots to read while humans stay on the surface. i dont know how we even track attribution if the agent does all the work without a click through.
full read: https://www.schemaapp.com/schema-markup/preparing-for-the-agentic-web-key-insights-from-rv-guha-and-schema-app/
ai agents for mva and architecture
another way to bloat the stack. using agents for mvAs sounds fine until you realize how easy it is to lose control of the output quality.>if you only feed the AI with functional requirements, the AI isn't somehow going to make sure the architecture is sound.
ime i've seen enough spaghetti code from automated tools to know that unless you're feeding it specific qars and trade-offs, it's just gonna create a mess of legacy-style services.
full read: https://www.infoq.com/articles/ai-agents-improve-software-architecture/?utm_campaign=infoq_content&utm_source=infoq&utm_medium=feed&utm_term=global

microsoft's doc intelligence sdk is actually kinda interesting
i was reading up on using Document Intelligence SDK to clean up those messy pdf inputs for rag pipelines since getting actual structured data out of a scanned invoice or receipt is such a headache. it's pretty cool how they have these prebuilt models like prebuilt-layout that can just spit out markdown, but i'm skeptical about the effort needed for custom extraction when you're dealing with weirdly formatted templates.>Most "RAG over PDFs" pipelines have a step nobody talks about much: something has to turn a scanned invoice, a multi-column contract, or a photographed receipt into text a model can actually reason over.
it seems like a lot of the heavy lifting is just managing those long-running operations with the poller, which sounds like a fun way to introduce latency if you aren't careful. i wonder how much the classifiers actually help when you're hitting it with a huge mix of unknown document types at once?
article: https://dzone.com/articles/microsoft-foundry-document-intelligence-sdk

speculative preloading for lcp images
was staring at some terrible lcp numbers on a client site today. they're loading every single image in the gallery with priority instead of just the top one. if you don't usefetchpriority="high"on that first hero image, you're basically asking for a bad core web vitals score.
<img src="/hero.jpg" fetchpriority="high" alt="main banner">
it's a tiny change but it actually works when the main thread is busy. anyone else seeing huge delays on mobile despite having a good server response time?
agency tool bloat is getting ridiculous
im so tired of seeing agencies just add random subscriptions every time someone hires a new lead or a client asks for something weird. saw this bit about jetoctopus tracking what ai bots actually see and how it maps fixes directly to logs>hand them over a fix already mapped
sounds cool but honestly sounds like more work for the dev team if we just dump a massive list of automated recommendations on them without checking first.
https://jetoctopus.com/top-technical-seo-tools-for-agencies/
enterprise ai security feels like a lot of hand-waving
The idea that we can just rely on data classification and prompt hygiene to stop sensitive info from leaking through an API is pretty optimistic.>Every prompt is an egress point.
It's easy to say we need access controls, but how do you actually audit free-text prompts for leaks in real time? I'm not seeing any actual proof that these architecture patterns work once you scale up RAG or agentic workflows beyond a small test group. There are way too many uncontrolled variables here to think a layered defense is enough without seeing some long-term testing data.
https://dzone.com/articles/enterprise-ai-data-security
jetoctopus stealth mode is basically just rate limiting
another way to waste time.>It's built for crawling websites with anti-scraping measures through pace.
link: https://jetoctopus.com/seo-competitive-analysis-in-jetoctopus/

JSON-LD fragmenting in large paginated lists
I am seeing some weirdness with how Google picks up the breadcrumb schema when it is injected via a client side script after the initial HTML load. I tried moving the script to the head and even hardcoding the first few items into the server side template, but the rich results keep dropping off on page five and beyond.
preconnect bloat isnt as bad as everyone says
seeing all these preconnect hints everywhere and people freaking out about lcp is getting old. apparently it only really hits you when you're on a cripplingly slow connection like 0.1 mbps. anything beyond the first few hints doesn't even move the needle much, so i don't see why we bother stressing over every single third-party origin.article: https://www.debugbear.com/blog/excessive-preconnect-hints

product snippet for aggregate rating schema
i'm tired of seeing people manually hardcode every single review into their json-ld. if you've got a dynamic list, just pull the counts and averages from your database into this structure instead."aggregateRating": {"@type": "AggregateRating","ratingValue": "4.8","reviewCount": "124"}don't forget to update the count on every new submission or google's just gonna flag it as fake data. anyone else still doing this via a python script?
image dimensions in search console errors
client's site was getting flagged for missing width/height attributes on every single image. chrome devtools shows it fine but gsc is still screaming about layout shifts. people think it's just a css issue. it isn't. if the browser doesn't know the aspect ratio before the pixels load, you're dead. i checked the srcsets and they were basically useless for preventing cls. found this fix for their template engine.<img src="image.jpg"width="800"height="600"alt="description">
just hardcode the dimensions in the html. it doesn't matter if your css makes it responsive with width: 100% and height: auto. the browser needs those intrinsic dimensions to reserve the space. i've seen too many devs skip this because they think modern browsers are smart enough. they aren't.
>modern browsers handle layout automatically is a lie. it's just more work for us when gsc starts reporting massive cls spikes. use the attributes or stop complaining about core web vitals scores.

code review is for learning not just bug hunting
saw some stats that incidents per pr are up over 240% lately. it's pretty wild because everyone thinks ai helps with speed but it's clearly just making things more unstable. the whole point of reviews isn't even about catching errors, it's mostly just so we don't lose the mental model of how the system actually works. if you stop reading diffs and just rely on 'swiss cheese' layers like agents and linters, you're basicallymore here: https://thenewstack.io/kill-code-review-theater/
CLS issues with font-display swap
Changing my CSS tofont-display: swapis killing my CLS on pages with heavy custom typography.
>The layout shifts every time the fallback font loads
It's
geo is just seo with a fancy name
another day, another buzzword. people are calling it generative engine optimization now like that changes anything. im seeing all this talk about making sure html isn't dependent on javascript just so claude or perplexity can read it.>we must also consider that a necessary condition for being cited
it's the same old crawlability garbage we've been dealing with for years. just because they call it a response engine doesn't mean the fundamentals are different. if the structured data is trash, you aren't getting cited regardless of what you call it. im pretty sure most of these "new" tactics are just basic semantic markup.
full read: https://www.debugbear.com/blog/technical-seo-checklist

screaming frog at brightonseo again
the frog team's heading to stand 18 for the next brightonseo. they're pushing those two-week trials for SEO Spider and the log file analyser, which is fine but i've already got plenty of licenses lying around. seeing all that talk about green seo lately makes me wonder if they'll actually show any real tech updates or just more merch. at this rate, i'll just be collecting another branded water bottle.https://www.screamingfrog.co.uk/blog/the-brightonseo-crawling-clinic-april-may-26/
claude code for log triage
piping raw logs into claude -p to flag failed payloads sounds great until you realize how much junk my plumber client's site spits out. i'm skeptical about using a CLAUDE.md file to act as the single source of truth for architecture when half my devs don't even document their own simple css changes.full read: https://dzone.com/articles/claude-enterprise-integration

using breadcrumbs to map site structure
breadcrumbs are a decent shortcut for mapping large ecom sites when url folders are a mess. i'm tired of squinting at crawl depth or internal linking graphs just to find the real logic behind some bloated category tree.>the actual logic behind content categorisation and the architectural decisions made at a business level
using screaming frog and some python scripts to build a visual tree model sounds fine, but i doubt it'll work for my current client with their broken schema. it's probably just more manual cleanup for us
found this here: https://www.screamingfrog.co.uk/blog/reconstructing-site-architecture-using-breadcrumbs/
schema isn't all the same for ai
everyone's acting like schema is useless because some studies show zero correlation with citations, but they're ignoring the actual connection part.>connecting their relationships across your website
it's not just about having a recipe or product tag on a page anymore. wells fargo supposedly fixed an inaccurate overview in hours by using this 'content knowledge graph' stuff to link entities. i don't know if i'm ready to commit to that level of semantic infrastructure for a client site. it sounds like a nightmare to maintain
link: https://www.schemaapp.com/schema-markup/not-all-schema-markup-is-equal-for-supporting-ai-responses/
shopify hero section bloat
seeing another guide obsessing over lcp scores is exhausting. most people just dump 900kb images in the header and wonder why it's laggy.>aim to keep the hero image under 180kb
imo if you can't get your assets under that limit, your dev team is
full read: https://www.debugbear.com/blog/shopify-speed-optimization
marketing vs dev speed wars
marketing loves dropping third-party scripts and heavy assets without checking anything first.>Marketing: Assessing high-level UX and SEO performance
it's always easy to blame the devs when the crux metrics tank because of some new tracking pixel. how do you guys actually stop the marketing side from breaking your lcp?
link: https://www.debugbear.com/blog/marketing-dev-collaboration

LCP issues with large hero images on mobile
Found another site where the LCP is tanking because they're serving the same huge desktop-sized image to everyone. Try testing your current hero setup by forcing a smallersrcsetfor mobile viewports and see if it actually moves the needle in your lab tests.
coding is barely 16 percent of our week
Spent way too much time reading about how we're basically just orchestrating agents now instead of actually building things. It claims we lose more than 8 hours a week just to fragmented workflows and context switching.>Coding makes up only 16 percent of a developer's time
Sounds about right, most of my day is just digging through Jira or tracing microservices when something breaks. The idea that 64 percent of orgs are already generating most of their code with AI feels like a massive stretch for any codebase with real legacy debt. It's fine for boilerplate but I don't see it handling complex system design anytime soon. Still, if it can automate the documentation part, i'm not complaining.
full read: https://hackernoon.com/ai-assisted-software-development-at-scale-from-code-generation-to-engineering-agents?source=rss

mcp might actually fix this mess
finally sounds like someone gets how much i hate writing custom function schemas for every single provider. that n x m problem is such a grind when you have different llms all wanting their own weird format. seeing json-rpc 2.0 used as the backbone makes sense though. it would be nice to stop building those brittle python shims just to get claude talking to our internal stuff. still dont know how oauth 2.1 is gonna play out with all the scaling issues in production. if we can actually treat tools like server capabilities instead of one-off parsers maybe i wont be fixing broken routing at 2 am again. hope it isnt just more hype for the sake of hype.link: https://dzone.com/articles/mcp-production-guide